
内容
# LLMSwap — One interface for every LLM. One Best Answer.
[](https://pypi.org/project/llmswap/)
[](https://pepy.tech/projects/llmswap)
[](https://github.com/sreenathmmenon/llmswap/actions/workflows/comprehensive-ci.yml)
[](https://www.python.org/downloads/)
[](https://github.com/sreenathmmenon/llmswap/blob/main/LICENSE)
Ask one model, compare many, or synthesize one cross-checked answer. LLMSwap is
an open-source Python SDK, CLI, and local Arena for working directly with 10 LLM
providers through one interface.
Bring your own provider keys, keep control of routing, and switch models without
rewriting the surrounding application or workflow. Use LLMSwap for applications,
analysis, operations, research, automation, learning, and everyday decisions.
- **Ask** any supported provider through the same Python API or CLI.
- **Compare** multiple models side by side in the local Arena.
- **Create a Best Answer** from independent drafts, with agreement,
disagreements, and cautions kept visible.
- **Connect tools and data** through function calling and local stdio MCP.
- **Operate with visibility** through provider diagnostics, token usage,
latency, optional caching, fallback, and cost estimates.
**Providers:** OpenAI, Anthropic, Gemini, Cohere, Perplexity, IBM watsonx, Groq,
Ollama, xAI, and Sarvam.
## New in 5.7.0
### Best Answer
Best Answer generates two to five independent responses and asks a judge model
to synthesize one result. It returns the answer plus agreement level,
agreements, disagreements, cautions, normalized token usage, latency, judge
identity, and optional candidate details.
```bash
llmswap --provider openai best \
"Which rollout plan has the lowest operational risk?"
```
The privacy-aware default keeps candidates and judge on the same provider and
model. Cross-provider synthesis is blocked until it is explicitly enabled.
Agreement is a cross-check signal, not a guarantee of factual truth.
### Installation diagnostics
`llmswap doctor` checks the active Python and CLI, `.env` discovery, provider
credentials and SDKs, configured models, and MCP prerequisites. It reports
whether a secret is configured without printing the secret value.
```bash
llmswap doctor
llmswap doctor --provider openai --live
llmswap doctor --format json
```
`--live` makes real provider calls and may incur provider usage.
## Quick start
Install LLMSwap:
```bash
# pip
python -m pip install llmswap
# or an isolated CLI installation with uv
uv tool install llmswap
# local browser Arena
python -m pip install "llmswap[web]"
```
Set at least one provider key:
```bash
export OPENAI_API_KEY="your-key"
# or ANTHROPIC_API_KEY, GEMINI_API_KEY, GROQ_API_KEY, XAI_API_KEY,
# COHERE_API_KEY, PERPLEXITY_API_KEY, SARVAM_API_KEY, or WATSONX_API_KEY
```
Then validate and ask:
```bash
llmswap doctor
llmswap --provider openai ask "Explain this proposal in plain language"
llmswap --provider openai chat
```
If keys are stored in `~/.env`, load them into the shell before ordinary CLI
commands:
```bash
set -a
source ~/.env
set +a
```
Best Answer and `doctor` also discover `.env` in the current directory and
`~/.env` without overriding already exported values.
## Python SDK
### One provider
```python
from llmswap import LLMClient
client = LLMClient(provider="openai", model="gpt-5.6")
response = client.query("Summarize the trade-offs in this decision")
print(response.content)
print(response.provider, response.model, response.usage)
```
Omit `provider` to auto-detect the first configured provider:
```python
client = LLMClient()
```
Pass an explicit model ID to use a model that is not in LLMSwap's curated
catalog. LLMSwap forwards it to the provider; the provider still determines
availability, account access, regional access, and validity.
### Best Answer
```python
from llmswap import LLMClient
client = LLMClient(provider="openai", model="gpt-5.6")
result = client.best_answer(
"Which option is most robust, and what could make it fail?"
)
print(result.best_answer)
print(result.agreement_level)
print(result.disagreements)
print(result.cautions)
print(result.total_usage)
```
Choose distinct providers with explicit consent:
```python
result = client.best_answer(
"Compare these two proposals",
models=["openai:gpt-5.6", "sarvam:sarvam-105b"],
judge="openai:gpt-5.6",
allow_cross_provider_sharing=True,
)
```
Cross-provider mode sends candidate response text to the selected judge
provider. LLMSwap anonymizes candidate labels and treats candidate text as
untrusted data, but it does not automatically redact sensitive content. See
[Security](https://github.com/sreenathmmenon/llmswap/blob/main/SECURITY.md).
### Tool calling
Define a tool once and offer it to supported providers:
```python
from llmswap import LLMClient, Tool
weather = Tool(
name="get_weather",
description="Get current weather for a city",
parameters={"city": {"type": "string"}},
required=["city"],
)
client = LLMClient(provider="anthropic")
response = client.chat("What is the weather in Tokyo?", tools=[weather])
```
Tool schemas are supported by Anthropic, OpenAI, Gemini, Groq, and xAI. Your
application remains responsible for implementing tools, validating arguments,
executing them, and returning results.
### Async client
```python
import asyncio
from llmswap import AsyncLLMClient
async def main():
client = AsyncLLMClient(provider="gemini")
response = await client.query("Give me three ways to reduce queue latency")
print(response.content)
asyncio.run(main())
```
## CLI
```bash
# Ask and chat
llmswap --provider anthropic ask "Explain this document"
llmswap --provider anthropic chat
# Cross-checked result
llmswap --provider openai best "Assess this migration plan"
llmswap --provider openai best "Assess this migration plan" --format json
# Inspect and verify providers
llmswap providers
llmswap providers --provider openai --verify
llmswap doctor
# Focused workflows
llmswap review app.py --focus security
llmswap debug --error "IndexError: list index out of range"
llmswap generate "Python function that validates a CSV header" --language python
# Usage and cost-estimate views
llmswap usage --days 7
llmswap compare --input-tokens 1000 --output-tokens 300
llmswap costs
```
Run `llmswap --help` or `llmswap <command> --help` for every option.
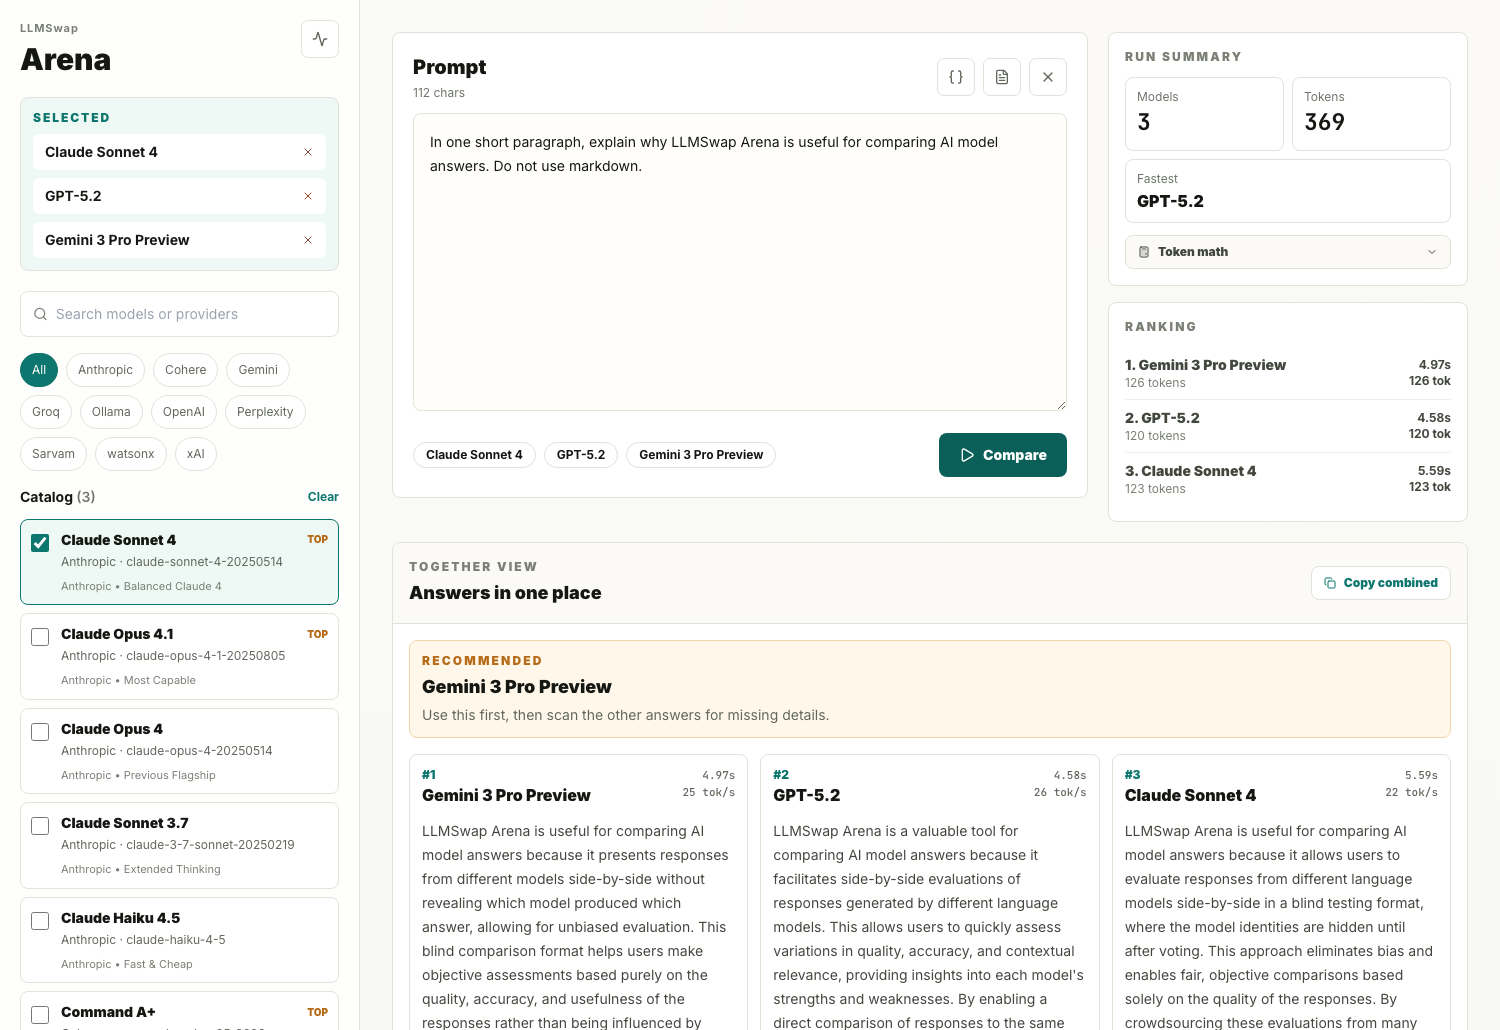
## Arena
The Arena runs locally and compares selected provider models in a browser:
```bash
python -m pip install "llmswap[web]"
llmswap web
```
It shows ranked responses, latency, and token usage. After a comparison, choose
**Create Best Answer** to synthesize the responses already on screen. Because
the candidates are reused, this action adds only the judge request.
## Best Answer request and privacy model
```text
Prompt ─┬─> Candidate A ─┐
├─> Candidate B ─┼─> Judge ─> Best Answer
└─> Candidate C ─┘ + agreement
+ disagreements
+ cautions
```
Candidates execute concurrently; judging starts after at least two candidates
succeed. The default three candidates plus one judge means four provider
requests. Provider billing and retention policies apply.
Same-provider mode is the default. If a configuration would send candidate
outputs to a different provider, use the explicit consent option:
```bash
llmswap --provider openai best "Review this decision" \
--models openai:gpt-5.6 sarvam:sarvam-105b \
--allow-cross-provider-sharing --show-candidates
```
## MCP
LLMSwap can start a local stdio MCP server and let a selected LLM choose its
tools through natural language:
```bash
llmswap mcp --command \
npx -y @modelcontextprotocol/server-filesystem "$HOME/Documents"
```
Inside the session:
```text
> tools
> list files
> read README.md
> quit
```
Use a specific reasoning provider if needed:
```bash
llmswap mcp --provider openai --command \
npx -y @modelcontextprotocol/server-filesystem "$HOME/Documents"
```
The original `llmswap-mcp` executable remains available for compatibility.
Local stdio is the verified transport. The `--url` path is legacy experimental
support and does not implement modern MCP Streamable HTTP.
MCP servers run with the permissions of your process. Only use trusted servers
and grant the narrowest filesystem and network access possible.
## Workspaces
A workspace stores project context, learnings, and decisions under `.llmswap/`:
```bash
cd /path/to/project
llmswap workspace init
llmswap workspace info
llmswap workspace journal
llmswap workspace decisions
```
Review workspace files before sharing a project because they may contain
sensitive context.
## Provider and model support
| Provider | Default model | Tool schemas | Setup |
|---|---|:---:|---|
| Anthropic | `claude-sonnet-5` | Yes | `ANTHROPIC_API_KEY` |
| OpenAI | `gpt-5.6` | Yes | `OPENAI_API_KEY` |
| Gemini | `gemini-3.6-flash` | Yes | `GEMINI_API_KEY` |
| Cohere | `command-a-plus-05-2026` | No | `COHERE_API_KEY` |
| Perplexity | `sonar-pro` | No | `PERPLEXITY_API_KEY` |
| IBM watsonx | `ibm/granite-4-h-small` | No | `WATSONX_API_KEY` + project ID |
| Groq | `openai/gpt-oss-120b` | Yes | `GROQ_API_KEY` |
| Ollama | `qwen3.5:9b` | No | Local Ollama server + pulled model |
| xAI | `grok-4.5` | Yes | `XAI_API_KEY` |
| Sarvam | `sarvam-105b` | No | `SARVAM_API_KEY` |
Defaults were audited on August 3, 2026. See [Provider and Model Support](https://github.com/sreenathmmenon/llmswap/blob/main/MODEL_SUPPORT.md)
for the complete catalog, lifecycle migrations, and official provider sources.
## Configuration
```bash
llmswap config show
llmswap config set provider.default anthropic
llmswap config set provider.models.openai gpt-5.6
llmswap config validate
```
Useful SDK controls:
```python
client = LLMClient(
provider="openai",
fallback=True,
cache_enabled=False, # opt in when responses are safe to retain
analytics_enabled=False, # opt in to local usage tracking
workspace_enabled=False, # disable project context discovery
)
```
Fallback does not guarantee availability. Cost output is an estimate and actual
provider billing may differ.
## How LLMSwap fits
These products solve adjacent problems:
| Product | Primary shape | A good fit when you need |
|---|---|---|
| **LLMSwap** | BYOK SDK, CLI, and local Arena | Direct multi-provider access, interactive comparison, and one cross-checked Best Answer |
| [**LiteLLM**](https://docs.litellm.ai/) | OpenAI-compatible SDK and proxy | Broad gateway compatibility, routing, budgets, and spend tracking |
| [**OpenRouter**](https://openrouter.ai/docs/guides/routing/provider-selection) | Hosted model and provider router | One hosted API that routes across model providers |
| [**Portkey**](https://portkey.ai/docs/product/ai-gateway) | AI gateway and observability platform | Centralized routing, guardrails, retries, budgets, and operational controls |
| [**Promptfoo**](https://www.promptfoo.dev/docs/intro/) | Evaluation and red-team framework | Repeatable prompt/model evaluation in local or CI workflows |
LLMSwap is strongest when people want to keep their own provider accounts and
move between asking, comparing, and synthesizing without deploying a gateway.
## Examples and documentation
- [Examples](https://github.com/sreenathmmenon/llmswap/tree/main/examples)
- [5.7.0 release notes](https://github.com/sreenathmmenon/llmswap/blob/main/docs/releases/5.7.0.md)
- [Provider and model support](https://github.com/sreenathmmenon/llmswap/blob/main/MODEL_SUPPORT.md)
- [Security policy and data flow](https://github.com/sreenathmmenon/llmswap/blob/main/SECURITY.md)
- [Changelog](https://github.com/sreenathmmenon/llmswap/blob/main/CHANGELOG.md)
- [Issue tracker](https://github.com/sreenathmmenon/llmswap/issues)
## Contributing
Issues and pull requests are welcome. Please include a focused reproduction and
tests for behavior changes. Never include real provider keys or sensitive prompt
data in reports or fixtures.
LLMSwap is released under the [MIT License](https://github.com/sreenathmmenon/llmswap/blob/main/LICENSE).
连接信息
猜你喜欢
暂无推荐服务器